Violetron
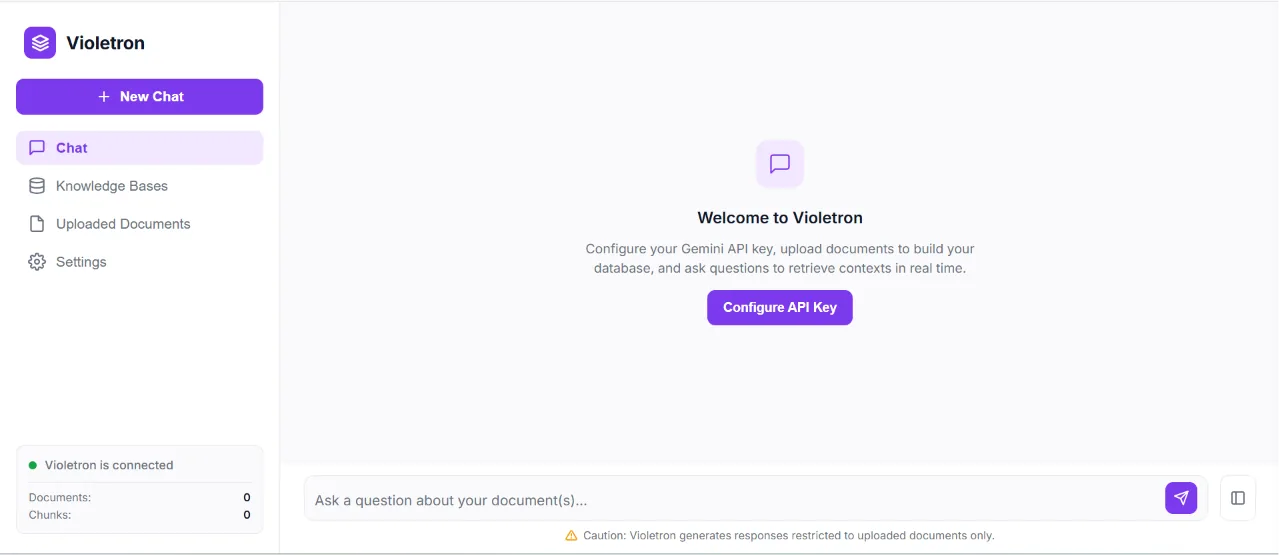
A document question-answering prototype built to demonstrate an end-to-end RAG pipeline, with the retrieved passages always visible, so the answer never feels like a black box.
Overview
Ask questions against your own documents
Upload a PDF or TXT file; questions are answered with Gemini, grounded in passages retrieved from that document.
Users upload documents, which are extracted, chunked, embedded and indexed for semantic retrieval. Questions are answered using Gemini with retrieved document passages supplied as grounding context: not fine-tuning, not model training.
RAG Pipeline
The complete retrieval chain, end to end
Processing & Retrieval
Chunking, embedding and search
Extraction
Text is extracted and normalized from PDF or TXT (not OCR) before being split into sentence-aware, word-targeted chunks.
Embeddings
Document chunks are converted into Gemini embeddings and stored in an in-memory FAISS IndexFlatL2 vector index.
Query matching
Questions are embedded with the same system; the closest chunks are retrieved for answer generation.
Transparency
Every answer shows its sources
Retrieved passages are placed directly into the answer prompt, and stay visible to the user afterward.
Users can inspect the passages retrieved for any question: filename, chunk number, the retrieved passage itself, and a retrieval-distance UI representation. That match figure is a relative ranking signal, not a calibrated confidence score.
Workspace
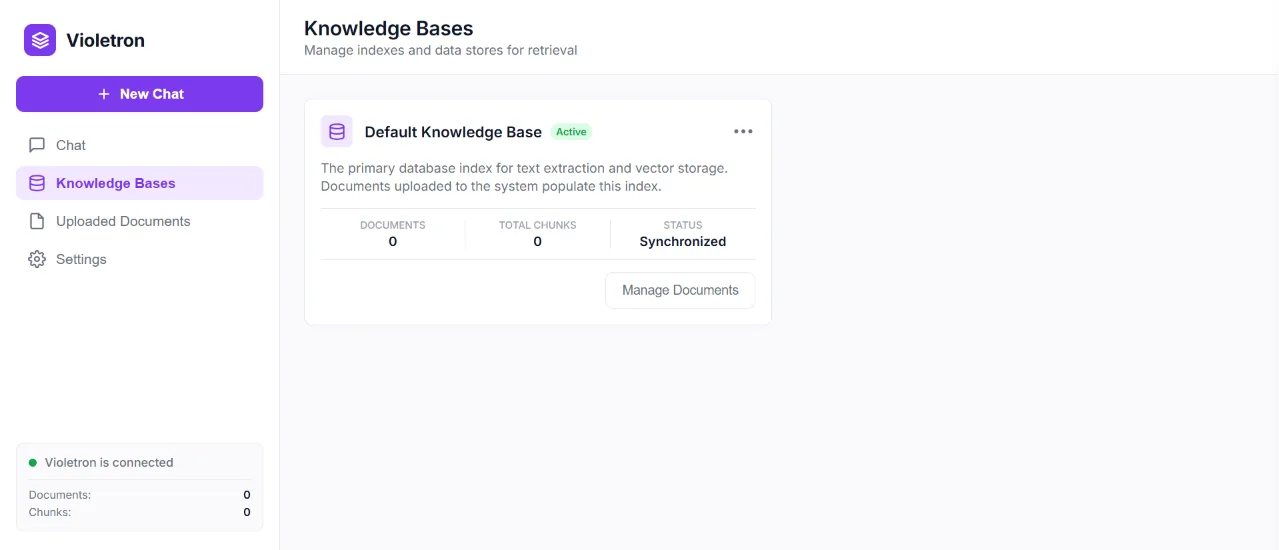
One knowledge base, many documents
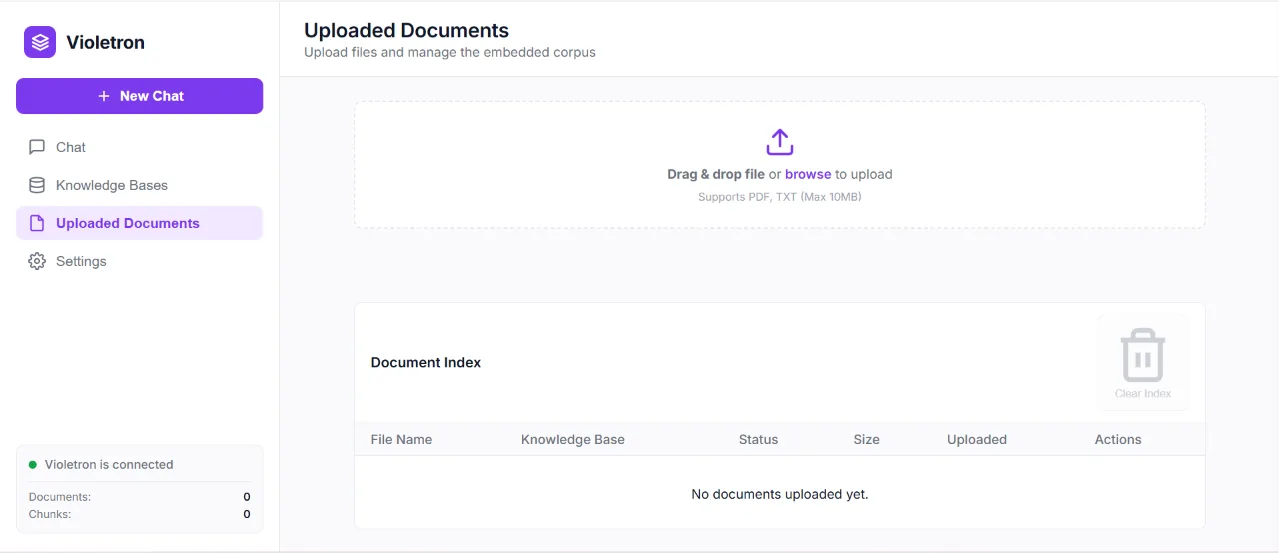
Users can upload multiple documents into the same knowledge base and inspect the document list: an in-memory vector index rather than a persistent vector database, by design for a focused prototype.
Stack
Technology
Frontend
Backend
AI & Retrieval
Documents